LLM-as-Judge Prompt Architecture for Multi-Step Agents
Judge prompts built for single outputs fail to catch errors buried in agent traces.
A standard LLM-as-Judge prompt scores one input and one output. Applied to a multi-step agent, that same prompt evaluates the wrong thing entirely, because the agent never produced a single output in the first place. It produced a sequence of decisions, and fixing the mismatch takes a different prompt architecture, not a sharper rubric.
Why a Judge Prompt Built for a Single Output Cannot Evaluate a Multi-Step Agent
A team runs a small golden test set through a judge, sees good scores, and ships. That contract stays the same when the evaluand is a multi-step agent, but the agent itself has changed shape underneath it.
What the agent actually produced is a trace: a plan, a series of tool calls with arguments and return values, reasoning between those calls, and only at the end, an answer. A judge prompt built for single outputs never asks to see any of that. The same survey finds that these judges can't react to real-world observations, so a judge that only sees the final response has no access to the decisions that actually determined whether the work was any good.
That gap produces failures a single-output judge cannot detect even in principle. If a tool was called with a malformed argument on step 4, the final answer can still read as correct, fluent, and confident. A 2026 practitioner analysis by Talikot covers this from the deployment side: LLM-as-Judge failure modes are documented and systematic, yet most teams running these pipelines don't know about them, so the scores coming out of the judge run consistently more optimistic than the work actually deserves. The problem sits in what the judge is allowed to see, not in how carefully the judge is asked to think. No amount of rubric tuning fixes a scope error. A judge whose context window never contained the tool calls cannot be prompted into scoring the tool calls.
What a multi-step agent trace contains
A judge can't score what it never receives, so building a working judge prompt starts with mapping what a trace actually holds, not with writing criteria. A trace is not a transcript of conversation. It bundles the original task or instruction, a planning step where the agent decides what to do and why, each tool call along with its name, its arguments, and the value it returned, any retrieval results pulled in along the way, the reasoning that connects one step to the next, and finally the output itself. Every one of those pieces is a place where something can go wrong, and every one of them is invisible to a judge that only receives the last item on the list.
The MAM framework, in a version updated in 2026, states the standard shape of a judge prompt: it typically includes the original task or request, the agent's output, and the evaluation criteria. That structure works for single-turn systems. For an agent, "the agent's output" has to stop meaning the final answer and start meaning the full sequence of actions that produced it, because the failures that matter happen inside that sequence, not after it.
Five categories of failure live inside a trace and nowhere else: planning errors, tool errors, retrieval errors, reasoning errors, and safety or policy violations. It means structuring each tool call as a record: the tool's name, the arguments passed to it, the value it returned, and the reason the agent gave for calling it. It means exposing the agent's intermediate reasoning or scratchpad at each step, where reasoning errors appear, and including the final output as the last item in a sequence. Knowing what belongs in the prompt is only half the job. Once that material is in front of it, the judge still needs to be told what it's actually scoring.
Structuring evaluation criteria for agentic behavior
Giving the judge the right material doesn't fix anything on its own if the criteria still apply to the trace the way they'd apply to a single output. A term like "correctness" means something different depending on where in the trace it gets applied, and criteria that stay fixed across the whole sequence will miss that.
The dimensions a single-output judge already knows how to use, correctness, relevance, factual grounding, completeness, still matter, but they leave out the behaviors that make agents fail. A handful of dimensions only make sense once they're pinned to a specific step. Policy and constraint compliance asks whether the agent stayed inside its declared boundaries at every decision point along the way, not only in the sentence it wrote at the end. Escalation clarity asks whether the agent flagged uncertainty and asked for help before pushing forward on a guess.
Policy compliance is the clearest case of why this has to be step-assigned. Checked only against the final answer, policy compliance tells you whether the sentence the agent produced violates a rule. Checked at the tool-call step, it tells you whether the agent was already past the point of no return, say, it issued a refund or sent an email, before anything in the final answer gave a reviewer a reason to look closer. Those are two different questions, and a judge prompt that asks only the second version of the question under the first version's label will pass agents that violated policy in the middle of their work and simply wrote a clean summary afterward.
The ATP-Bench three-agent architecture builds this principle directly into its design. A Precision Inspector scores whether each tool call was necessary and correctly specified. Keeping criteria attached to the step where they apply avoids that. In practice, a judge prompt built this way should move through the trace step by step, state which criteria apply at that step, give a rubric for each one, and ask for both a score and a short written reason. That reason is the one piece of the output that reveals when a score looks fine but the judge's actual reasoning underneath it doesn't hold up.
How Single-Judge Architectures Break Down
Even with the right context and the right step-assigned criteria, a single judge working through an entire trace runs into the same overload problem the trace structure was meant to solve. Splitting judges by role or by segment of the trace produces steadier results than asking one judge to carry every dimension at once.
Two specific pressures cause a single judge to degrade on long traces. One is positional: a judge reading a trace in sequence tends to give later steps less scrutiny than earlier ones, simply because attention across a long context window isn't even. The other is a kind of self-consistency pressure: once a judge has scored step 3 as acceptable, it has some pull toward scoring step 5 the same way, even when step 5 is wrong on its own terms and has nothing to do with step 3.
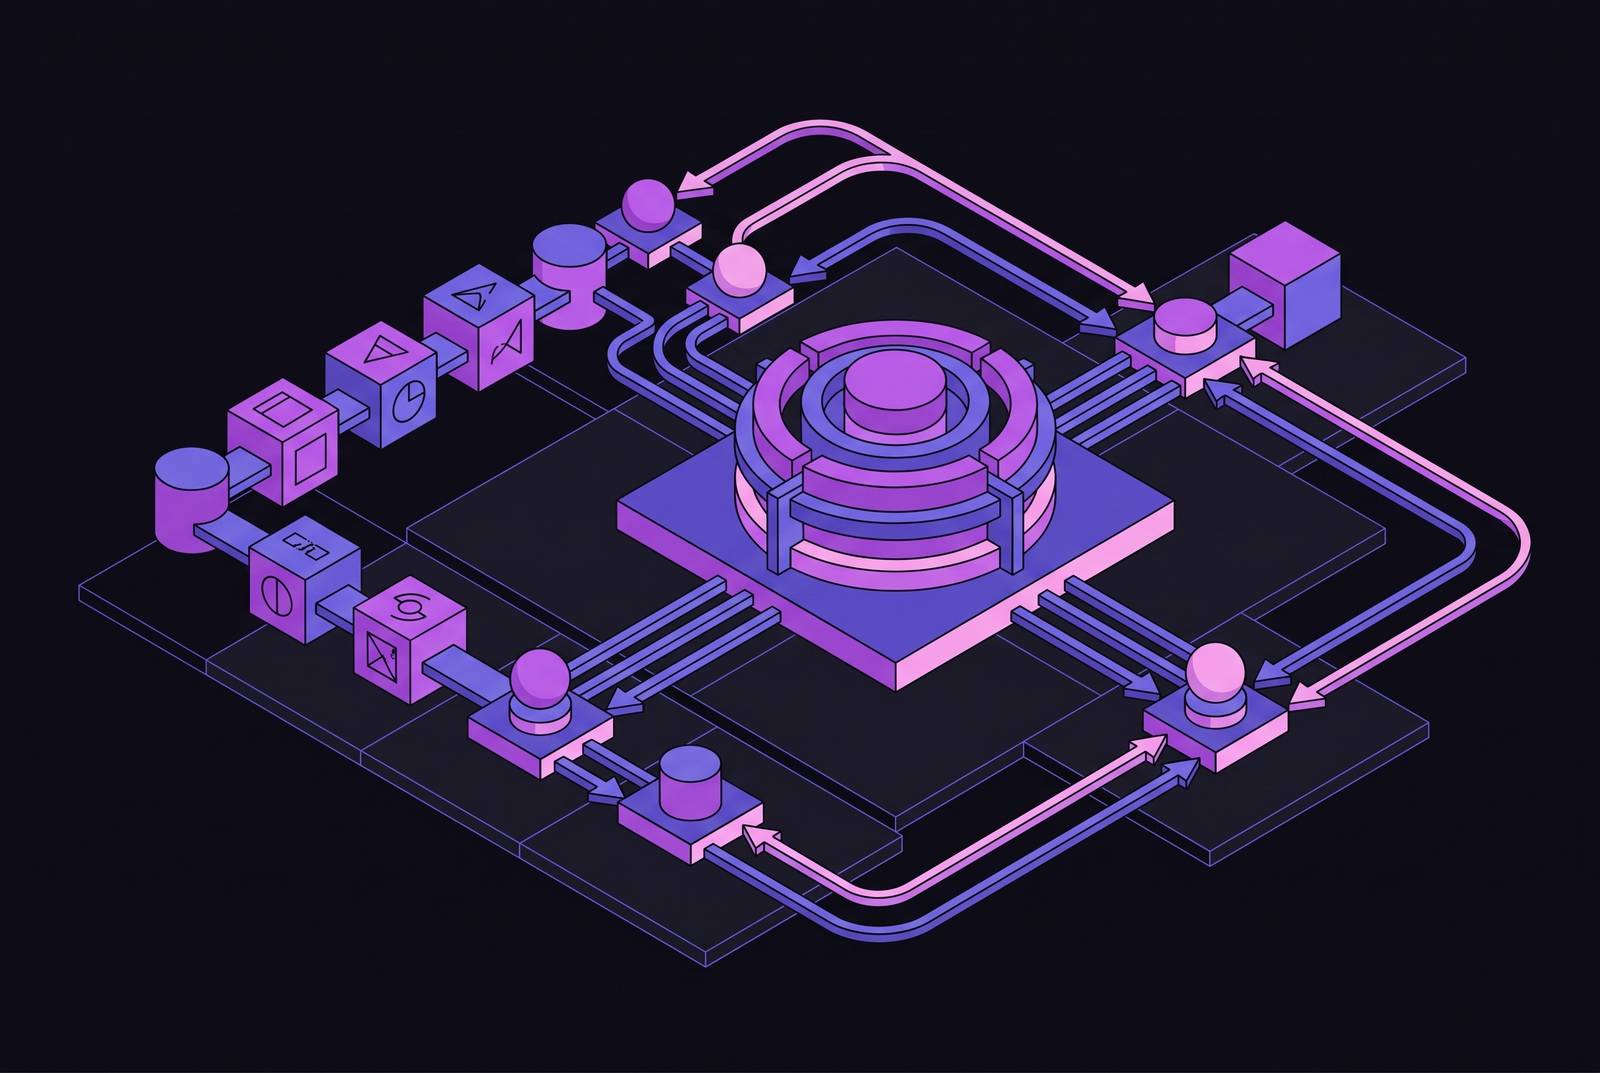
A multi-agent judge pattern answers this by splitting the work across specialized agents rather than asking one agent to hold the whole trace in mind at once. The core idea is several specialized LLM agents working through an evaluation together, each producing part of the judgment under a defined protocol, with their outputs combined through a set aggregation step. The broader Agent-as-a-Judge literature describes two topologies that recur across these systems. In Collective Consensus, agents debate the same question until an arbiter settles on a verdict. In Task Decomposition, agents specialize by rubric dimension or by segment of the trace, and a higher-level module fuses their separate outputs into one. Task Decomposition fits agent traces more naturally, because it lines up directly with the step-assigned criteria described above: each specialist judge owns a slice of the trace or a dimension of the rubric, and nobody is asked to hold the whole thing in their head at once.
ATP-Bench's three-agent design gives this a concrete shape. The Chief Judge then receives both inspectors' reports along with the final output and synthesizes all of it into a single score on a 0 to 100 scale. Keeping the Precision Inspector and the Recall Inspector apart matters specifically because it separates false positives in tool planning from false negatives, something a single judge handling both at once tends to blur together.
None of this means multi-judge setups win by default. The choice comes down to the shape of the trace. A multi-judge architecture earns its added complexity when traces run too long for one judge to track reliably, when different segments of a trace call for different domain expertise, or when a production system needs a score at every step. A single judge remains the right tool for short traces with only a few tool calls, for offline batch evaluation where the cost of synthesizing multiple judges' outputs outweighs the benefit of finer granularity, or as a quick first-pass filter ahead of closer review. The right answer follows from how the trace is structured.
The context the judge prompt must include and its format for reliable scoring
Once the architecture is settled, whether that's one judge or several, the actual prompt needs a defined structure: a role declaration, the task instruction, the trace itself in a labeled format, criteria tied to specific steps, and a fixed output format. Skipping or reordering any of these pieces reproduces the same failures at the prompt level that a mismatched architecture would cause at the system level.
The prompt needs to open by telling the judge that it is evaluating, because models that are strong at following instructions sometimes try to complete the task themselves. Right after that comes the original task instruction, given word for word, placed before any part of the trace, so the judge's standard for what counts as correct comes from the agent's actual goal rather than something inferred after the fact from what the agent happened to do. Then comes the trace, labeled by step type, PLAN, TOOL_CALL, TOOL_RESULT, REASONING, OUTPUT, so the judge can parse the structure directly from marked steps. After each step or step type, a block should spell out exactly which criteria apply there and what a passing score looks like for that step, because criteria embedded inline with the trace keep the judge from defaulting to treating every dimension as if it applies equally to the whole thing. The prompt should close by requiring a structured object as output: a score per criterion per step, a short rationale attached to each score, and one aggregate verdict, since this is easier to parse automatically and commits the judge to a position.
A stripped-down skeleton makes the ordering concrete:
A few formatting choices cut down on bias beyond just getting the fields right. And the rationale field isn't something to cut for brevity. You et al.'s point about cognitive overload applies here directly: a judge asked to juggle a multifaceted rubric in one pass tends to produce coarse scores that miss the specific thing that went wrong, and requiring a rationale for every criterion forces the judge to show its work rather than pattern-match its way to a number.

## Positioning judge evaluation in the agent workflow and acting on what it returns

Judge evaluation earns the most value when it runs on the trace itself, not only on the final output, and the point in the workflow where it runs determines what a team can actually do with the result. Run against a live trace mid-execution, a step-level judge can catch a malformed tool argument or a policy violation before the agent moves on to the next step, which means a bad tool call gets flagged and corrected rather than discovered only after it shaped three more decisions downstream. Run after the fact against a completed trace, the same judge prompt turns into a diagnostic tool: it points at the specific step where reasoning broke down, instead of only reporting that the final answer was wrong.

What a team does with the score depends on where the evaluation sits. A step-level flag mid-execution can trigger a retry at that step, a request for human review before the agent proceeds, or an automatic halt if the flagged step involved an irreversible action like a write or a purchase. A post-hoc batch evaluation across many traces serves a different purpose: it surfaces which step type produces the most failures across a large sample, whether that's tool argument errors, missed retrieval opportunities, or reasoning that drifts from the stated task, and that pattern should drive where engineering effort goes next, not just which individual trace gets flagged. A score with no rationale attached gives a team nothing to act on beyond a number. A score paired with a rationale and tied to a specific step tells the team exactly which part of the agent's design needs attention, whether that's the tool's input schema, the retrieval step's context window, or the planning prompt itself. The judge's output is only as useful as the trace it was built to see, and a team that builds that trace carefully, labels it clearly, and routes the judge's findings back to the specific step that produced them gets an evaluation system that actually improves the agent, rather than one that just produces a reassuring number at the end.
Sources
- 2026-1-8 A Survey on Agent-as-a-Judge Runyang You*1 Hongru Cai*1 Caiqi Zhang2
- Catching One in Five: LLM-as-Judge Blind Spots in Production Multi-Turn Transaction Agents
- Multi-Agent-as-Judge: Aligning LLM-Agent-Based Automated Evaluation with Multi-Dimensional Human Evaluation - ACL Anthology
- Benchmarking LLM Judges for Mobile Agent Evaluation